Dataset
Input
Input unavailable. Try another representation.

Do Video Models Render What the Program Specifies?
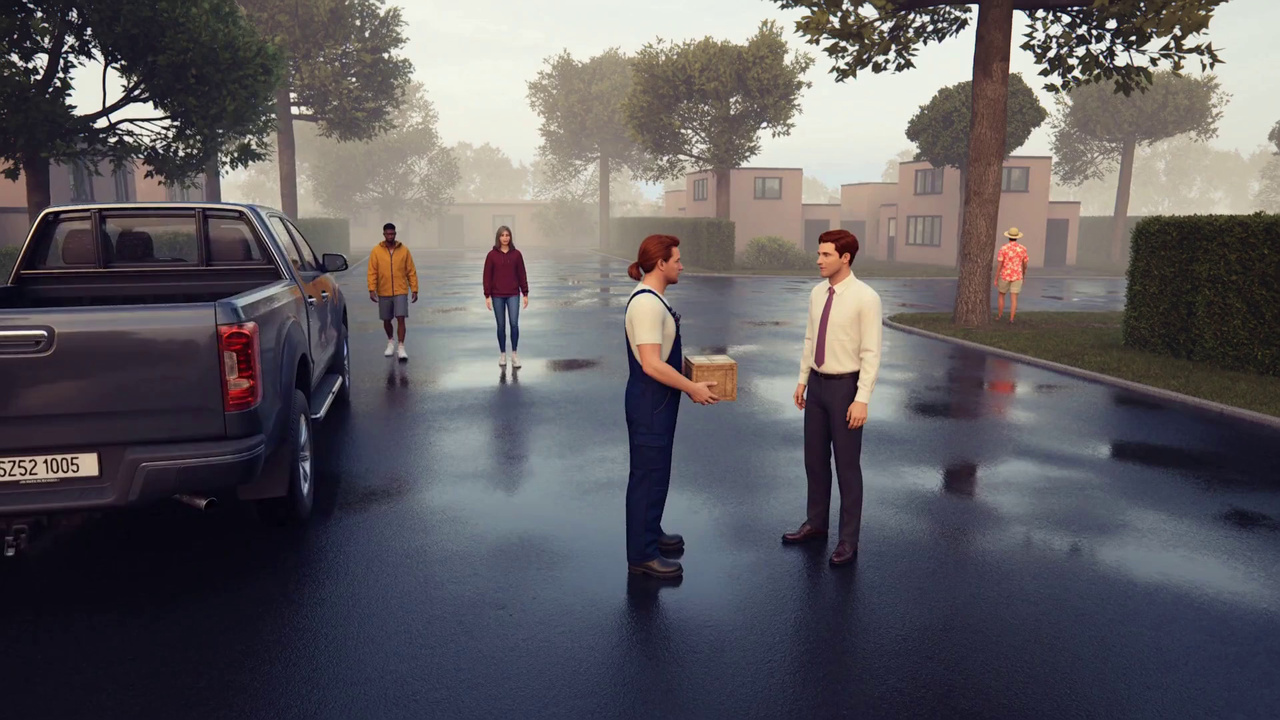
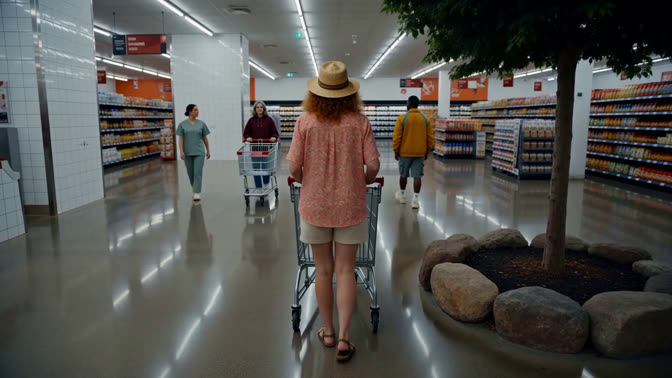
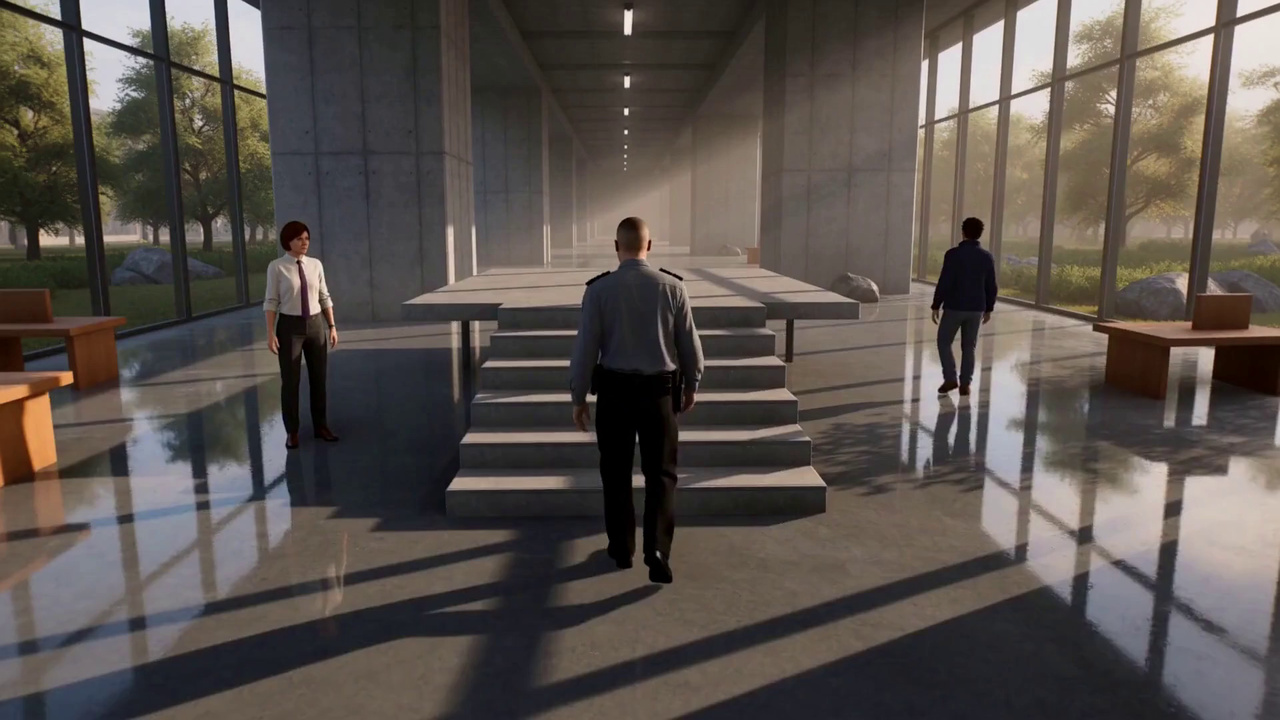
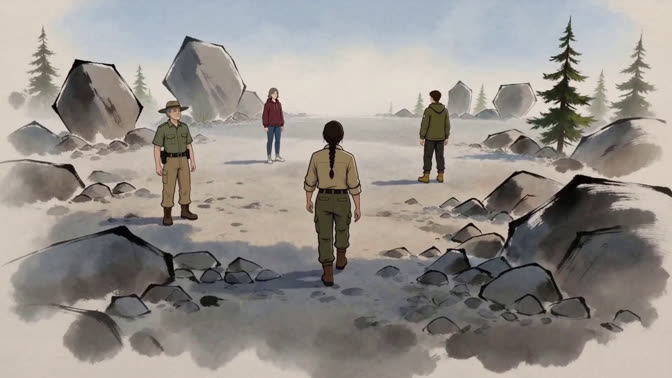
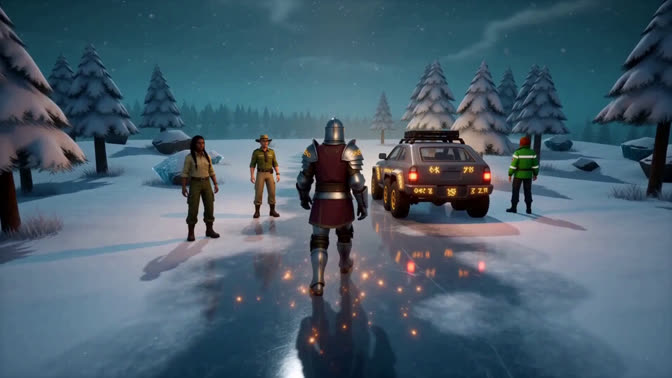
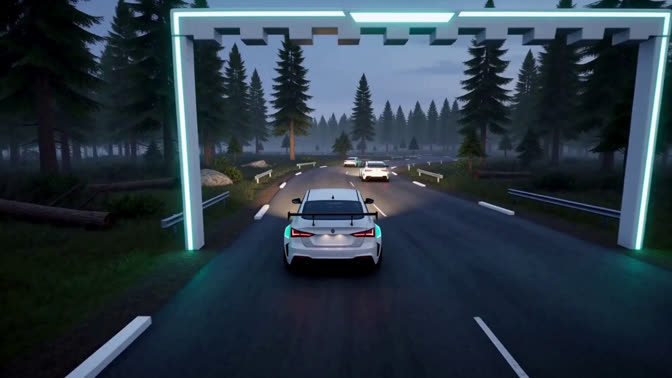
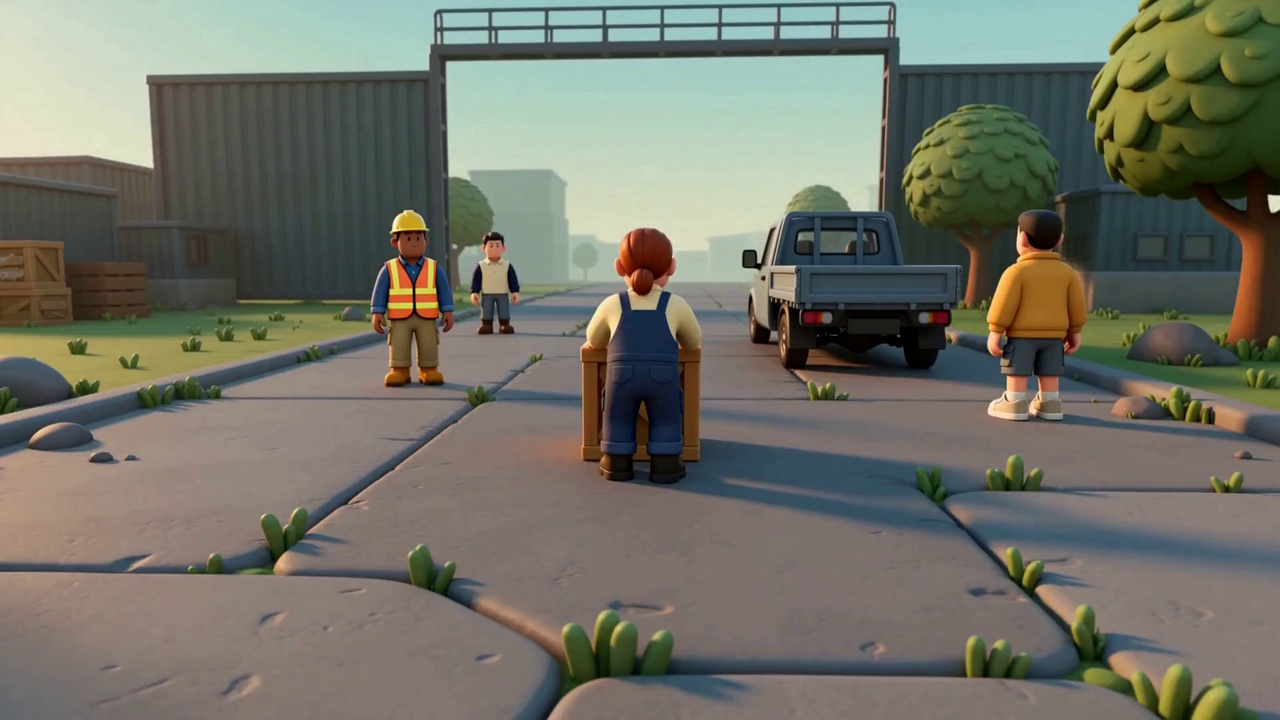
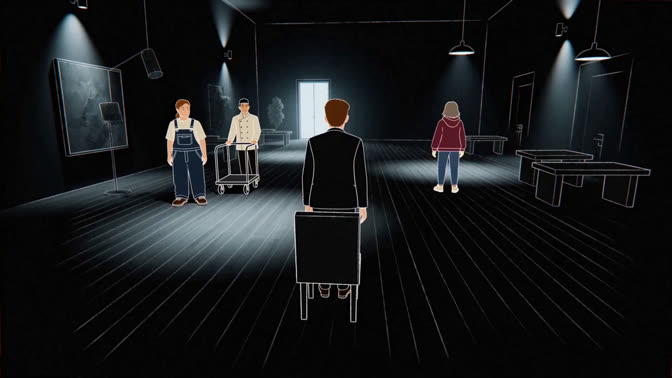
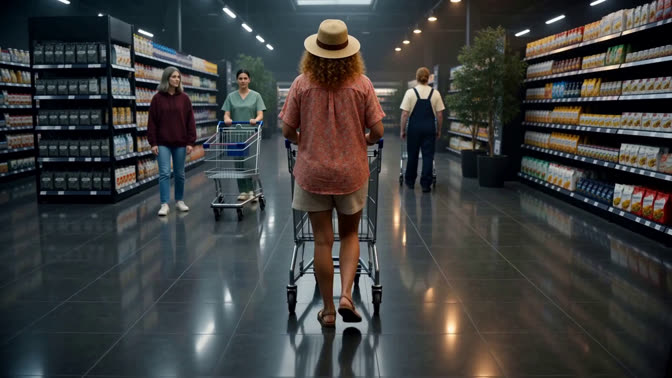
PROWBench checks whether generated videos faithfully realize program-specified entity trajectories, camera motion, and interactions, using replayable world states and timestamped events as the reference.
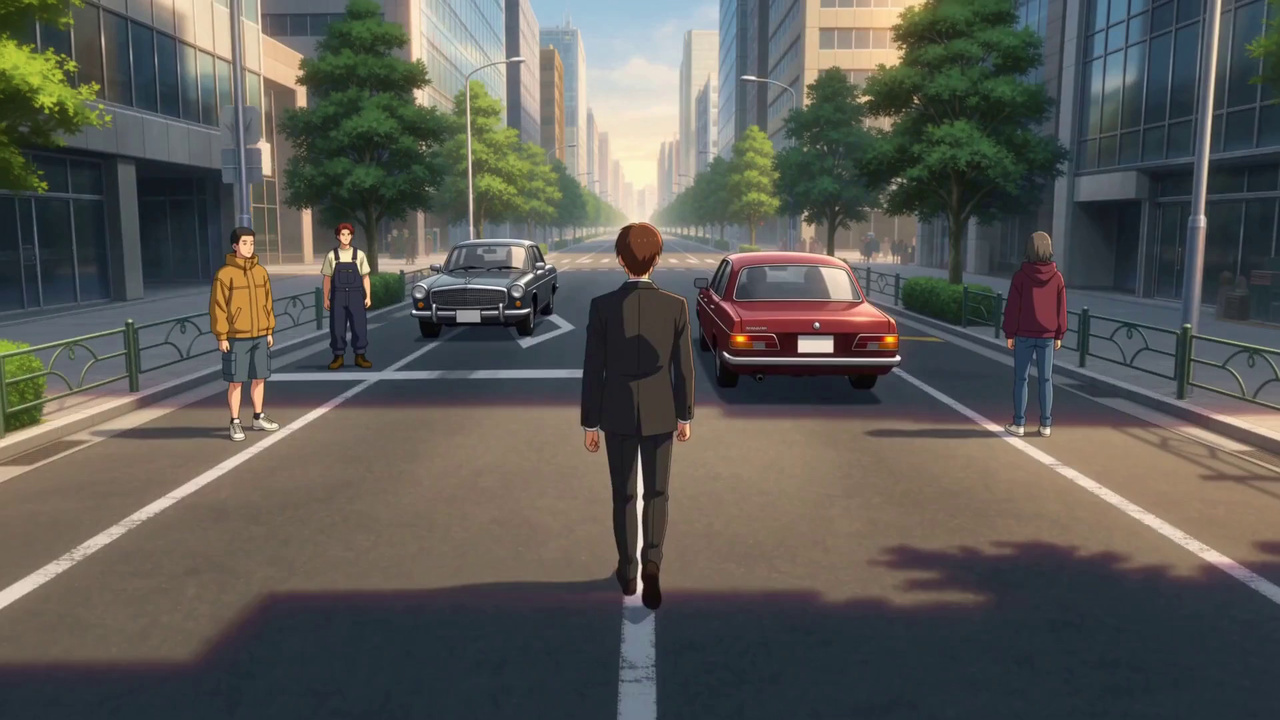
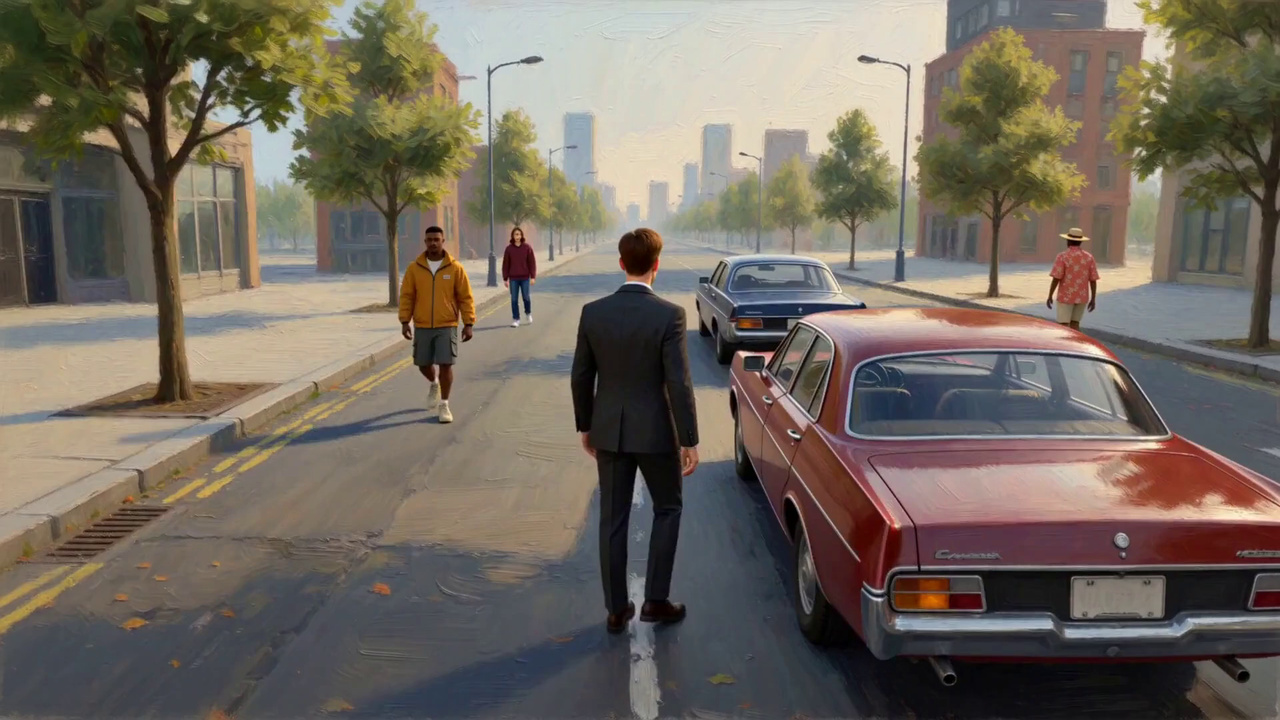
Coarse 3D, CWM proxy, and Colored-OBB are rendered from the same recorded world state and camera trajectory. The world record retains entity states and events even outside the camera’s field of view.
Video unavailable. Use the video link below.
Video unavailable. Use the video link below.
Video unavailable. Use the video link below.
Press Play to load this example.
This gallery shows a subset of the benchmark results.
Input unavailable. Try another representation.
Press Play to load the selected videos.
480p uses less data; 720p shows more detail. Lower-resolution originals keep their native size and are marked on the method card. For multi-view, the resolution refers to the complete four-view grid.
Selected gallery: 20 Verified-FF and 25 Unverified-FF examples on disjoint scenes, 6 multi-view examples × 4 cameras, and 6 long-horizon examples × 30 seconds. Input representations ↗
This gallery presents a selection of the supplied qualitative clips. The paper additionally evaluates 20 Gunfight cases and a fifth multi-view method, Seedance 2.5; those outputs are not available in this gallery. See the paper for quantitative results and evaluation protocols.
40 Verified-FF appearance references